Search News
TerraVista Metrics (TVM)Industry Portal
TerraVista Metrics (TVM)Hot Articles
TerraVista Metrics (TVM)- How to Evaluate Spark Plug Suppliers for Consistent Quality and Lead TimesSpark plugs supplier evaluation guide: compare quality control, traceability, fitment, total cost, and reliable lead times to secure dependable engine maintenance supply.
- What Drives System Interoperability Testing Service Costs in Complex Projects?System interoperability testing service cost depends on integration scope, workflows, environments, and assurance needs. Learn how to budget smarter and reduce project risk.
- Project Planning Sourcing Guides: How to Qualify Suppliers Before Work StartsSourcing guides project planning helps teams qualify suppliers before work begins—verify compliance, delivery capacity, financial strength, and sustainability to reduce risk and protect project outcomes.
Popular Tags
TerraVista Metrics (TVM)Industry NewsHow to Choose Industry Benchmarking Tools That Deliver Actionable Performance Insights
auth.Time
Oct 07, 2026Click Count
The right industry benchmarking tool does not merely rank suppliers, assets, or competitors. It creates a defensible link between a business decision and the operating evidence behind it: verified product performance, lifecycle cost drivers, regulatory exposure, supply-chain reliability, and the conditions under which a result remains valid.
That distinction matters most where a poor specification decision becomes expensive to reverse. A modular accommodation unit that performs well in a temperate showroom may have inadequate thermal behavior in a humid coastal site. A hotel automation platform may demonstrate polished guest-facing features while creating integration, cybersecurity, or data-ownership problems. A benchmark is actionable only when it reveals these operational differences before capital is committed.
Start with the decision that the tool must improve
“Industry benchmarking tools” covers a wide range of databases, scorecards, test laboratories, market-intelligence platforms, compliance trackers, and supplier-assessment systems. Choosing among them by interface quality, report volume, or the number of available indicators produces weak outcomes because those features do not establish decision relevance.
The more useful question is: What decision will change if the benchmark produces a different result? The answer determines the evidence required.
- For a new tourism development, the central issue may be whether an asset design will meet site-specific durability, energy, maintenance, and permitting requirements over its intended service life.
- For procurement of outdoor equipment or hospitality furnishings, the critical issue may be whether apparent purchase-price savings survive heavy usage, replacement cycles, warranty constraints, and supplier lead-time risk.
- For smart hotel systems, the decision may turn on interoperability with existing property-management, access-control, payment, and network systems rather than on the number of functions shown in a product demonstration.
- For attractions and public-use infrastructure, the decisive evidence may concern safety documentation, inspection needs, fatigue behavior, serviceability, and the availability of qualified maintenance support.
A tool that is excellent for market positioning may be unsuitable for technical procurement. Likewise, a laboratory report may establish material or system performance but offer little help in comparing commercial availability across regions. The strongest tool selection often combines evidence sources, but each source should have a clearly defined role rather than being treated as interchangeable “data.”
Distinguish a benchmark from a score
Scores are attractive because they simplify comparison. Their weakness is that they can obscure the assumptions that matter. A composite sustainability, quality, or supplier-risk score may be useful for screening a long list, but it should not become the sole basis for approving a high-value or operationally critical purchase.
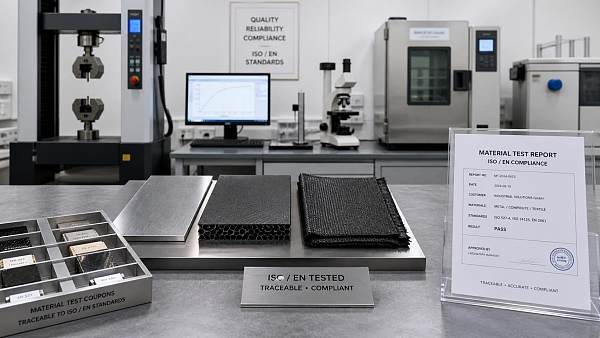
A meaningful benchmark preserves the underlying measurement logic. It should show what was measured, how it was measured, the reference standard or comparison group, the date of the evidence, and the relevant operating conditions. Without those elements, a rating is an opinion presented with numerical precision.
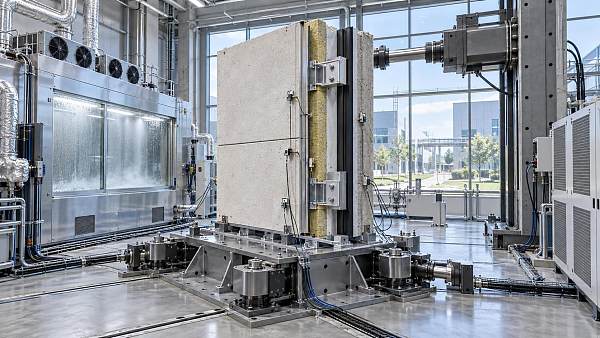
Consider thermal performance in prefabricated structures. A single insulation value is not enough to determine whole-building energy behavior. Thermal bridging, air leakage, window performance, orientation, local climate, ventilation strategy, installation quality, and occupancy patterns can materially affect outcomes. A tool that reports only a headline figure may aid early filtering, but it cannot support a final specification decision.
The same issue appears in digital systems. A benchmark that labels a platform “integrated” should identify the integration method: native connection, documented API, middleware dependency, custom development, or manual data exchange. These routes have different implementation costs, failure points, update burdens, and accountability structures. A broad capability label does not reveal them.
Test whether the underlying data is decision-grade
Data quality is not defined by volume. It is defined by traceability, comparability, and fitness for the decision at hand. Before selecting a platform or provider, examine the evidence chain behind a sample output.
Traceability means that a result can be connected to a named product configuration, model version, supplier entity, test method, source document, and reporting date. This is particularly important when specifications change frequently, suppliers operate through distributors, or a system contains software and hardware components from several parties.
Comparability means that items are assessed using sufficiently consistent definitions and conditions. Comparing furniture abrasion results generated under different methods, or comparing energy claims based on dissimilar climate assumptions, can create a false ranking. A serious benchmarking tool should either normalize the comparison or state clearly why direct comparison is not valid.
Fitness means that the available data reflects the operating environment. Tourism assets frequently face concentrated guest use, seasonal peaks, transport constraints, local utility limitations, salt exposure, high humidity, ultraviolet exposure, remote-service conditions, or multilingual regulatory documentation. Generic commercial data often misses these conditions.
Ask for a sample report rather than relying on a dashboard demonstration. A useful report should make it possible to answer practical questions such as:
- Which performance claims are independently tested, and which are supplier-declared?
- What configuration was assessed, and could a change in materials, firmware, installation method, or component sourcing invalidate the conclusion?
- Which assumptions are embedded in lifecycle, energy, carbon, or reliability estimates?
- Can the original source material be reviewed during procurement, engineering approval, or a dispute?
- Does the report identify evidence gaps rather than converting missing information into an apparently neutral score?
Tools that expose uncertainty are generally more useful than those that conceal it. Missing evidence is itself a procurement finding, especially where safety, compliance, environmental claims, or public-use durability are involved.
Make sure benchmarks reflect operating conditions, not ideal conditions
Many poor investment decisions originate in a gap between nominal performance and deployed performance. Benchmarking systems should help close that gap by allowing users to apply contextual filters and scenario assumptions.
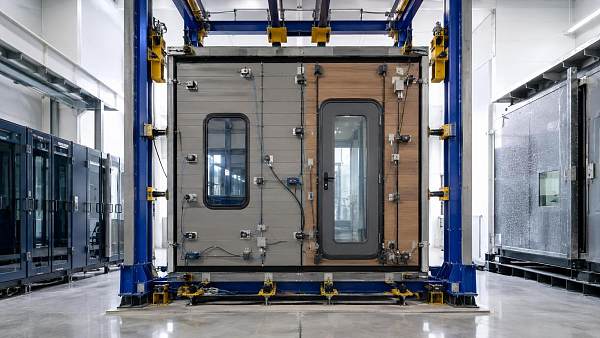
For physical assets, relevant filters may include climate zone, wind and snow load, corrosion category, usage intensity, cleaning regime, expected occupancy, local repair capability, and transport route. A cabin intended for a remote destination, for example, should be assessed not only for delivered condition but also for site assembly tolerance, component replacement logistics, foundations, drainage, and access for future maintenance.
For hospitality technology, context includes network resilience, device density, data-residency requirements, user permissions, local technical support, and the property’s existing application landscape. A platform’s feature set matters less than whether it can operate reliably during connectivity interruptions, integrate without excessive custom work, and provide a workable exit path if the vendor relationship changes.
Scenario capability is therefore a major selection criterion. The tool should allow a decision team to see how the preferred option changes under realistic conditions: higher energy prices, longer replacement lead times, harsher weather, reduced occupancy, a different jurisdiction, or a stricter maintenance interval. If the output remains identical regardless of context, it is likely a catalog rather than a decision instrument.
Evaluate lifecycle consequences rather than purchase-price comparisons
Benchmarking should reduce the tendency to treat acquisition cost as total cost. This is especially relevant for assets exposed to high guest turnover or public usage, where damage rates, cleaning, downtime, maintenance access, and replacement parts affect operating economics.
A lifecycle comparison does not require false precision. It does require a transparent structure that separates the cost elements most likely to differ between options:
A tool need not calculate every cost automatically. More importantly, it should identify which costs are evidenced, which are modeled, and which require local validation. A single total-cost figure without stated inputs can be less reliable than a structured comparison with visible ranges and assumptions.
Check how the tool handles compliance across jurisdictions
Compliance analysis is often treated as an administrative add-on to technical selection. In cross-border projects, it can alter the viable supplier pool, construction method, installation schedule, insurance position, and cost base.
Useful tools distinguish among mandatory legal requirements, recognized technical standards, third-party certifications, test reports, and voluntary supplier claims. These categories are not equivalent. A product tested to one standard is not automatically approved for every jurisdiction, and a certification may apply only to a specified factory, component, product variant, or production period.
The tool should also make its jurisdictional boundaries explicit. It should not imply legal approval merely because a product has documentation from another market. Where local interpretation, authority approval, or project-specific engineering sign-off is required, that limitation should be visible in the output.
This is especially important for modular construction, electrical systems, amusement hardware, fire-related components, and connected devices handling personal data. In these categories, an incomplete documentation trail can create delays long after the commercial comparison appears complete.
Assess supplier intelligence separately from product performance
A technically strong product and a dependable supply relationship are different propositions. Industry benchmarking tools often combine them into one vendor score, which can hide the source of risk.
Product assessment should address performance, configuration control, durability, safety, and compatibility. Supplier assessment should examine manufacturing consistency, quality-management evidence, production capacity relative to demand, export documentation, warranty administration, spare-parts commitments, financial exposure where relevant, and the clarity of contractual responsibilities.
Separating these views is valuable when a product is sourced through a distributor, assembled locally, or dependent on several upstream manufacturers. It prevents a well-known brand, attractive reference list, or polished sales process from substituting for evidence about the exact supply chain that will support the asset.
The frequency of updates matters here. Supplier information can become stale faster than technical specifications. A platform should state when supply-chain, ownership, compliance, and availability data was last reviewed, and how material changes are captured. Historical data is useful for identifying patterns, but decisions on live projects require current validation.
Examine methodology, governance, and commercial independence
A benchmark carries authority only to the extent that its methodology can be examined. The provider does not need to disclose proprietary analytical models in full, but it should explain source categories, weighting principles, inclusion rules, conflict controls, and review processes.
Questions worth asking include whether suppliers pay for inclusion or enhanced visibility, whether sponsored listings are visually separated from analytical conclusions, whether suppliers can challenge factual errors, and whether report revisions are version-controlled. These are not minor governance details. They determine whether a ranking can be defended internally and externally.
Commercial independence is particularly significant where the tool is used to compare suppliers competing for a major contract. If revenue depends heavily on supplier participation, a decision team should understand whether this influences coverage, scoring, or access to unfavorable findings. A tool can remain useful under a commercial model, but its incentives should be visible.
Prioritize usability at the point of decision
A technically rigorous tool can still fail if its outputs cannot move through the approval process. Decision-grade usability is not the same as visual simplicity. It means the tool can translate complex evidence into records that engineering, procurement, finance, operations, and legal review can interrogate without losing the original context.
Look for configurable comparison criteria, exportable evidence, clear version history, source links, assumption logs, and the ability to retain project-specific comments or approval status. These features create an audit trail. They also reduce the common problem of teams debating different versions of the same claim in spreadsheets, presentations, email threads, and supplier documents.
Integration should be judged carefully. A tool does not need to connect to every enterprise system to be valuable. But if it is expected to support recurring sourcing decisions, asset portfolios, or compliance monitoring, its data should be exportable in a format that can be reconciled with procurement, asset-management, or project-control records. A closed platform that cannot provide its evidence in usable form can create a new dependency rather than reducing risk.
Use a pilot to test decisions, not features
The most reliable way to select a benchmarking tool is to apply it to a real, bounded decision with competing options and known evidence gaps. Avoid a pilot based solely on clicking through features. Instead, test whether the tool changes the quality, speed, and defensibility of a pending evaluation.
A suitable pilot might compare several shortlisted accommodation systems for a defined site, evaluate competing smart-room architectures against an existing hotel technology stack, or assess commercial-grade furnishing options against a required maintenance profile. The exercise should require the tool to handle incomplete documentation, conflicting claims, local constraints, and lifecycle trade-offs—the conditions under which superficial benchmarks usually break down.
The result should not be judged by whether the platform produces a winner. A better outcome may be the identification of missing tests, incompatible assumptions, underestimated installation costs, or supplier obligations that must be clarified before selection. Actionable performance insight often narrows uncertainty rather than manufacturing certainty.
The best industry benchmarking tools make decisions more rigorous without pretending that every decision can be automated. They reveal the evidence behind a claim, keep context attached to a comparison, identify where validation is still required, and show how performance affects cost, compliance, resilience, and operational outcomes. That is the standard worth applying when the consequences of being wrong extend well beyond the purchase order.
Recommended News
 Sep 27, 2026How to Design Scalable System Integration Testing for Multi-Vendor DeploymentsScalable system integration testing for multi-vendor deployments: build resilient, secure, and growth-ready operations with proven interface, resilience, and acceptance strategies.
 Sep 24, 2026Hotel Tourism Benchmarking: Which KPIs Reveal Competitive Market Position?Tourism benchmarking for hotels reveals the KPIs that define competitive position, from RevPAR index and demand quality to profit, guest experience, and asset resilience.
 Sep 20, 2026Supply Chain Analysis: How to Identify Cost, Risk, and Lead-Time BottlenecksSupply chain analysis helps tourism project leaders uncover cost, risk, and lead-time bottlenecks—protecting opening dates, budgets, and guest-ready operations.
 Sep 19, 2026How to Choose Industry Benchmarking Tools That Deliver Actionable Performance InsightsIndustry benchmarking tools: learn how to validate data, compare lifecycle costs, assess compliance, and turn performance evidence into smarter decisions.
 Sep 14, 2026Engineering Performance Testing Trends Reshaping Product Validation WorkflowsEngineering performance testing trend analysis reveals how assembly validation, realistic environmental loads, and digital resilience improve product reliability and reduce field failures.
 Sep 12, 2026Cloud Integration Interoperability Testing: Methods, Metrics, and Release GatesSystem interoperability testing cloud integration: explore practical methods, key metrics, and evidence-based release gates for secure, reliable connected operations.
 Sep 05, 2026What Engineering Performance Testing Should Cover During a Specification ReviewEngineering performance testing for specification review: learn how to verify structural strength, durability, safety, sustainability, and system reliability before costly project decisions.
 Aug 11, 2026How to Evaluate Materials Performance Analysis Services in Europe for Compliance-Critical ProjectsMaterials performance analysis Europe: learn how to compare accredited labs, verify compliance readiness, and choose a provider whose data, methods, and reports stand up to real project scrutiny.
 Jul 27, 2026Product Application Analysis for Procurement: How to Compare Fit, Risk, and ROIProduct application analysis for procurement helps buyers compare fit, compliance risk, lifecycle cost, and ROI with confidence. Learn a practical framework to avoid costly sourcing mistakes.
 Jul 22, 2026How to Evaluate Weather Resistance in Materials Performance Analysis?Materials performance analysis weather resistance explained: learn how to assess UV, moisture, temperature, and corrosion risks to choose durable materials with confidence.
 Jul 15, 2026Cloud Storage for Business: How to Compare Security, Access Speed, and Backup CostsCloud storage for business: compare security, access speed, and backup costs with a practical framework to reduce risk, control spend, and choose the right provider with confidence.
 Jul 14, 2026What Are Standardized Performance Benchmarks Ratings Used For in Vendor Evaluation?Standardized performance benchmarks rating explains how buyers compare vendors with verified data on compliance, durability, and lifecycle value for smarter procurement decisions.
 Jul 13, 2026Product Benchmarking Rating Explained: How to Compare Scores Across SuppliersProduct benchmarking rating explained: learn how to compare supplier scores with confidence, verify methodology, spot hidden risks, and make smarter procurement decisions.
 Jul 13, 2026How to Choose a Product Benchmarking Data Provider for Reliable Market ComparisonsProduct benchmarking data provider selection starts with methodology, transparency, and sector fit. Learn how to compare providers for reliable market insights and smarter procurement decisions.
 Jul 10, 2026Technical Integration Resilience Explained: How to Reduce Downtime Across Connected SystemsTechnical integration resilience explained: learn how to reduce downtime, prevent cascading failures, and improve uptime across connected systems with practical planning insights.
 Jul 08, 2026How to Use Product Benchmarking KPIs to Compare Competing SolutionsProduct benchmarking KPIs help you compare competing solutions with real evidence. Learn how to measure performance, lifecycle cost, compliance, and risk for smarter buying decisions.
 Jul 05, 2026How to Run an Environmental Sustainability Assessment: Metrics, Boundaries, and Trend AnalysisEnvironmental sustainability assessment trend analysis made practical: learn how to set metrics and boundaries, compare lifecycle impacts, and turn sustainability data into smarter decisions.
 Jul 04, 2026Hospitality Design Benchmarks Metrics Explained: Which KPIs Matter for Guestroom Upgrades?Hospitality design benchmarks metrics explained: discover the KPIs that matter most for guestroom upgrades, from lifecycle cost and durability to energy use, maintenance, and guest satisfaction.
 Jul 02, 2026How to Compare Product Category Pricing Models for Better Margin PlanningProduct category pricing model comparison made practical: learn how to evaluate total cost, hidden risks, and lifecycle value to improve margin planning and make smarter sourcing decisions.
 Jun 30, 2026How Technical Explainer Content for Procurement Helps Compare Specs, Risks, and SuppliersTechnical explainer content for procurement helps teams compare specs, uncover supplier risks, and choose solutions that improve compliance, lifecycle value, and long-term performance.
 Jun 29, 2026System Interoperability Testing Vendors: Key Criteria for Compliance and PerformanceSystem interoperability testing vendors compared: discover how to assess compliance, performance, independence, and real-world reliability before costly integration failures happen.
 Jun 28, 2026Product Benchmarking Explained: How to Compare Performance, Cost, and QualityProduct benchmarking explained: learn how to compare performance, cost, and quality with a practical framework that reduces risk, improves supplier selection, and supports smarter long-term decisions.
 Jun 27, 2026How to Build a Product Benchmarking Comparison Matrix for Hospitality Equipment SelectionProduct benchmarking comparison matrix guide for hospitality equipment selection. Learn to compare cost, compliance, durability, and lifecycle value with confidence.
 Jun 25, 2026What Drives System Interoperability Testing Implementation Cost in Multi-Vendor Projects?System interoperability testing implementation cost rises in multi-vendor projects due to scope gaps, retesting, compliance, and downtime risk. Learn how to control costs early.
Quarterly Executive Summaries Delivered Directly.
Join 50,000+ industry leaders who receive our proprietary market analysis and policy outlooks before they hit the public library.