Search News
TerraVista Metrics (TVM)Industry Portal
TerraVista Metrics (TVM)Hot Articles
TerraVista Metrics (TVM)- How to Evaluate Spark Plug Suppliers for Consistent Quality and Lead TimesSpark plugs supplier evaluation guide: compare quality control, traceability, fitment, total cost, and reliable lead times to secure dependable engine maintenance supply.
- What Drives System Interoperability Testing Service Costs in Complex Projects?System interoperability testing service cost depends on integration scope, workflows, environments, and assurance needs. Learn how to budget smarter and reduce project risk.
- Project Planning Sourcing Guides: How to Qualify Suppliers Before Work StartsSourcing guides project planning helps teams qualify suppliers before work begins—verify compliance, delivery capacity, financial strength, and sustainability to reduce risk and protect project outcomes.
Popular Tags
TerraVista Metrics (TVM)Industry NewsHow to Design Scalable System Integration Testing for Multi-Vendor Deployments
auth.Time
Oct 07, 2026Click Count
How to Design Scalable System Integration Testing for Multi-Vendor Deployments
Multi-vendor tourism deployments demand more than individual product validation. A smart lock may work in a supplier demonstration, a building-management controller may pass its own factory test, and a modular cabin may arrive with compliant electrical components. None of that proves the destination will operate reliably when these assets exchange data, share power and networks, respond to faults, and support staff during a full occupancy period.
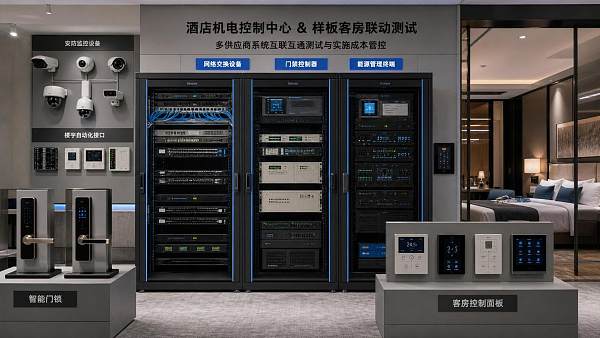
Scalable system integration testing is the discipline of proving those interactions before they become expensive site problems. It examines the operational system rather than isolated equipment: guest applications, property-management platforms, access control, HVAC, energy meters, alarm systems, attraction controls, Wi-Fi infrastructure, maintenance tools, and the physical environment in which they must coexist.
For technical evaluators, the objective is not to create the largest possible test plan. It is to establish evidence that the intended architecture can expand without creating hidden dependencies, unacceptable cybersecurity exposure, unsafe fallback behavior, or an unmanageable support burden. That requires a test strategy built around interfaces, operational journeys, and change—not vendor promises.
Start with the operating model, not the device inventory
A common early mistake is to list every purchased device and ask whether it connects. Connectivity is only the lowest level of assurance. A tourism site needs to know what should happen when a guest checks in late, when a cabin loses network access during severe weather, when an attraction enters a restricted operating mode, or when a housekeeping team changes a room’s service status while another system is issuing access credentials.
Build the test scope from critical operational journeys. In a resort or glamping development, these may include reservation-to-room assignment, digital check-in, occupancy-based energy control, emergency notification, incident logging, maintenance dispatch, and restoration after a power or communications interruption. In an attractions environment, include safe startup, controlled shutdown, operator handover, fault escalation, and interaction with ticketing or capacity-management systems where applicable.
Each journey should identify the initiating event, systems involved, expected data exchange, timing assumptions, accountable owner, manual fallback, and evidence required for acceptance. This approach exposes ambiguities that a device schedule conceals. For example, “door lock integrates with PMS” is not a usable requirement until the team defines when credentials are issued, revoked, refreshed, cached, audited, and recovered after a PMS or network outage.
Define the system boundary honestly
Integration scope should include systems that can affect the intended outcome, even when they are procured under different packages. A smart-room platform may depend on identity services, network time synchronization, mobile-device permissions, VLAN configuration, cloud APIs, and an electrical design that preserves essential controls during a short power disturbance. A thermal-control issue in a prefabricated unit may be physical rather than digital, yet it can still trigger unnecessary HVAC run time, guest complaints, and misleading energy-management data.
This is why multi-vendor testing needs both digital and engineering perspectives. TerraVista Metrics approaches tourism infrastructure through this wider lens: technical integration must be considered alongside structural resilience, commercial-grade durability, sustainability requirements, safety conditions, and long-term operability. The useful question is not merely whether an interface exists, but whether the complete destination can perform as designed under realistic constraints.
Create an interface baseline before integration begins
The interface baseline is the foundation of scalable system integration testing. It should be established before site commissioning, preferably before final procurement commitments make architecture changes difficult. This baseline is not a generic network diagram. It is a controlled record of how systems exchange commands, events, status information, files, identities, and alarms.
For every integration, document the protocol, version, direction of data flow, authentication method, ownership of each data field, update frequency, timeout behavior, retry policy, logging location, and expected behavior when the connection fails. Where a supplier uses a proprietary middleware layer, require enough technical documentation to test its dependencies and failure modes. “API available” does not establish whether the API supports the operational workflow, rate limits, error handling, or future version control needed by the project.
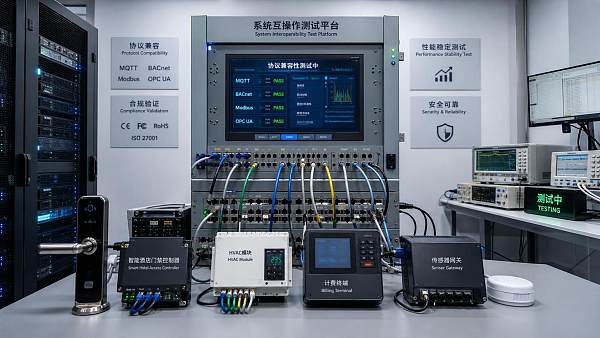
Open or widely implemented protocols such as BACnet, Modbus, OPC UA, MQTT, and OCPP can reduce integration friction in the right context, but protocol selection alone does not guarantee interoperability. Implementations vary. Object naming, permitted commands, data typing, security configuration, and optional features must be tested against the actual system design. Treat any claimed standard conformance as a starting point for verification, not as a substitute for it.
Use a layered test model to prevent late-stage surprises
A scalable program separates testing into layers. This prevents the project from discovering basic configuration defects during an expensive end-to-end commissioning window, when multiple vendors are on site and schedules are under pressure.
At the component level, confirm that each device, application, and controller meets its specified functions. At the interface level, verify message formats, permissions, command acknowledgement, error codes, and time synchronization between two systems. At the subsystem level, test complete functional groups such as a smart guest room, an access-control zone, a modular cabin cluster, or an attraction operating station.
End-to-end testing then proves the journey across ownership boundaries. Finally, operational acceptance testing should involve the people who will actually run the site: front-desk staff, security teams, maintenance personnel, safety officers, and operational managers. Their involvement matters because a technically successful transaction may still be operationally poor. A screen may display an alarm, for example, while failing to make clear who must respond, where the asset is located, or what the approved next action is.
The test environment should resemble production sufficiently to reveal real issues. It needs representative network segmentation, identity controls, firmware versions, data volumes, and configuration sets. A supplier’s isolated demonstration environment is useful for exploratory work, but it cannot prove behavior in the destination architecture. Where full physical replication is impractical, use a combination of representative hardware, simulators, controlled test data, and documented assumptions. Assumptions should be visible in the acceptance record rather than buried in a contractor’s notes.
Test scale as behavior, not just volume
“Scalable” is often reduced to a capacity claim: the platform supports more rooms, more sensors, or more users. In practice, scale changes system behavior. More connected units generate more events, more certificate renewals, more software updates, more competing commands, and a larger operational burden when something goes wrong.
Capacity tests should therefore reflect meaningful peaks rather than only average traffic. Consider a concentrated check-in period, a weather-related surge in HVAC commands, simultaneous reconnects after a network interruption, or a broad access-credential update following a group booking change. Observe response time, queue growth, dropped messages, database contention, alarm visibility, and recovery time. The acceptable thresholds must come from project requirements and risk tolerance; they should not be borrowed uncritically from a vendor’s typical deployment.
Growth should also be tested as an architectural event. Add a representative new cabin cluster, an additional hotel building, a new attraction zone, or a different supplier’s device family in a controlled test scenario. If expansion requires manual reconfiguration across many systems, undocumented naming conventions, or direct changes to production databases, the deployment may function today but is not genuinely scalable.
Resilience tests deserve equal weight
A reliable system is not one that never fails; it is one that fails in a controlled, understandable way. Test loss of internet connectivity, delayed API responses, inaccurate time sources, power restoration, partial network isolation, duplicate events, and unavailable cloud services. Verify local fallback controls, manual procedures, data reconciliation, and the point at which staff are alerted.
For safety-related functions, the responsible engineering team must determine applicable local codes, authority requirements, and manufacturer instructions. Operational technology dashboards, guest apps, or analytics platforms should not be permitted to introduce dependencies that compromise mandated safety behavior. Integration testing can demonstrate the interface behavior, but it does not replace the separate safety engineering, inspection, and compliance work required for the project.
Treat cybersecurity and data governance as testable requirements
Multi-vendor environments can accumulate risk quietly. A technician account retained after commissioning, a default password in an edge controller, an exposed remote-maintenance route, or a broad API token may create a more serious weakness than an obvious software defect. Testing should include account provisioning and removal, least-privilege roles, credential storage, patch responsibilities, remote access approval, event logging, and evidence that sensitive information is not unnecessarily shared between systems.
Network segmentation is particularly important where guest-facing systems, payment-related services, building controls, and safety infrastructure coexist. The exact controls depend on architecture and applicable obligations, but the principle is stable: a compromise or malfunction in one zone should not automatically provide access to every other zone. Test the segmentation itself. A network drawing is not proof that firewall rules, routing paths, device certificates, and maintenance access work as intended.
Data governance should answer equally practical questions. Which system is authoritative for guest status? How long are access events retained? Can energy data be traced to a physical meter and its calibration context? Who owns the data after a vendor contract ends? These are procurement and operating questions as much as technical ones, and they should be settled before integrations become embedded in daily operations.
Make acceptance evidence reusable
The final output of a testing program should be more useful than a signed checklist. Retain the approved architecture, interface register, test cases, results, defects, retest evidence, known limitations, configuration baseline, and operational runbooks. Record software and firmware versions, because a successful test result cannot be interpreted later without knowing what was actually tested.
Defects should be classified by operational consequence, not merely by technical severity. A minor display inconsistency may be tolerable. An intermittent mismatch between reservation status and access privileges is not, even if it appears only under a particular sequence of events. Acceptance criteria should state whether a defect requires correction, a documented workaround, a design change, or an explicit operational risk decision by the accountable owner.
Independent benchmarking can add value where suppliers provide incompatible claims or where the project combines manufactured assets with digital platforms from several markets. TerraVista Metrics focuses on converting technical characteristics, compliance considerations, and market intelligence into comparable evidence across eco-structures, smart hotel systems, outdoor infrastructure, attractions, and hospitality furnishing. That perspective is useful when integration decisions must account for durability, environmental conditions, lifecycle maintenance, and interoperability at the same time.
Build for change after handover
Integration testing should not end with opening day. Vendor updates, new guest services, replacement hardware, seasonal operating changes, and expanded site capacity can alter a previously stable system. Establish a change-control process that identifies affected interfaces, requires regression testing proportionate to risk, and keeps configuration records current. Even a small mobile-app update can affect identity flows, notification permissions, or access-control behavior.
The most durable strategy is one that makes dependencies visible and turns operational expectations into repeatable tests. Before approving a multi-vendor deployment, technical evaluators should be able to answer a few direct questions: what happens when a critical connection fails, who owns each interface, how does the system expand, what evidence supports acceptance, and which assumptions still require validation against site conditions or local requirements?
If those answers are unclear, more individual product testing is unlikely to solve the problem. The next step is to clarify the operating journeys, interface baseline, failure scenarios, and acceptance evidence before the destination architecture becomes harder to change.
Recommended News
 Sep 27, 2026How to Design Scalable System Integration Testing for Multi-Vendor DeploymentsScalable system integration testing for multi-vendor deployments: build resilient, secure, and growth-ready operations with proven interface, resilience, and acceptance strategies.
 Sep 24, 2026Hotel Tourism Benchmarking: Which KPIs Reveal Competitive Market Position?Tourism benchmarking for hotels reveals the KPIs that define competitive position, from RevPAR index and demand quality to profit, guest experience, and asset resilience.
 Sep 20, 2026Supply Chain Analysis: How to Identify Cost, Risk, and Lead-Time BottlenecksSupply chain analysis helps tourism project leaders uncover cost, risk, and lead-time bottlenecks—protecting opening dates, budgets, and guest-ready operations.
 Sep 19, 2026How to Choose Industry Benchmarking Tools That Deliver Actionable Performance InsightsIndustry benchmarking tools: learn how to validate data, compare lifecycle costs, assess compliance, and turn performance evidence into smarter decisions.
 Sep 14, 2026Engineering Performance Testing Trends Reshaping Product Validation WorkflowsEngineering performance testing trend analysis reveals how assembly validation, realistic environmental loads, and digital resilience improve product reliability and reduce field failures.
 Sep 12, 2026Cloud Integration Interoperability Testing: Methods, Metrics, and Release GatesSystem interoperability testing cloud integration: explore practical methods, key metrics, and evidence-based release gates for secure, reliable connected operations.
 Sep 05, 2026What Engineering Performance Testing Should Cover During a Specification ReviewEngineering performance testing for specification review: learn how to verify structural strength, durability, safety, sustainability, and system reliability before costly project decisions.
 Aug 11, 2026How to Evaluate Materials Performance Analysis Services in Europe for Compliance-Critical ProjectsMaterials performance analysis Europe: learn how to compare accredited labs, verify compliance readiness, and choose a provider whose data, methods, and reports stand up to real project scrutiny.
 Jul 27, 2026Product Application Analysis for Procurement: How to Compare Fit, Risk, and ROIProduct application analysis for procurement helps buyers compare fit, compliance risk, lifecycle cost, and ROI with confidence. Learn a practical framework to avoid costly sourcing mistakes.
 Jul 22, 2026How to Evaluate Weather Resistance in Materials Performance Analysis?Materials performance analysis weather resistance explained: learn how to assess UV, moisture, temperature, and corrosion risks to choose durable materials with confidence.
 Jul 15, 2026Cloud Storage for Business: How to Compare Security, Access Speed, and Backup CostsCloud storage for business: compare security, access speed, and backup costs with a practical framework to reduce risk, control spend, and choose the right provider with confidence.
 Jul 14, 2026What Are Standardized Performance Benchmarks Ratings Used For in Vendor Evaluation?Standardized performance benchmarks rating explains how buyers compare vendors with verified data on compliance, durability, and lifecycle value for smarter procurement decisions.
 Jul 13, 2026Product Benchmarking Rating Explained: How to Compare Scores Across SuppliersProduct benchmarking rating explained: learn how to compare supplier scores with confidence, verify methodology, spot hidden risks, and make smarter procurement decisions.
 Jul 13, 2026How to Choose a Product Benchmarking Data Provider for Reliable Market ComparisonsProduct benchmarking data provider selection starts with methodology, transparency, and sector fit. Learn how to compare providers for reliable market insights and smarter procurement decisions.
 Jul 10, 2026Technical Integration Resilience Explained: How to Reduce Downtime Across Connected SystemsTechnical integration resilience explained: learn how to reduce downtime, prevent cascading failures, and improve uptime across connected systems with practical planning insights.
 Jul 08, 2026How to Use Product Benchmarking KPIs to Compare Competing SolutionsProduct benchmarking KPIs help you compare competing solutions with real evidence. Learn how to measure performance, lifecycle cost, compliance, and risk for smarter buying decisions.
 Jul 05, 2026How to Run an Environmental Sustainability Assessment: Metrics, Boundaries, and Trend AnalysisEnvironmental sustainability assessment trend analysis made practical: learn how to set metrics and boundaries, compare lifecycle impacts, and turn sustainability data into smarter decisions.
 Jul 04, 2026Hospitality Design Benchmarks Metrics Explained: Which KPIs Matter for Guestroom Upgrades?Hospitality design benchmarks metrics explained: discover the KPIs that matter most for guestroom upgrades, from lifecycle cost and durability to energy use, maintenance, and guest satisfaction.
 Jul 02, 2026How to Compare Product Category Pricing Models for Better Margin PlanningProduct category pricing model comparison made practical: learn how to evaluate total cost, hidden risks, and lifecycle value to improve margin planning and make smarter sourcing decisions.
 Jun 30, 2026How Technical Explainer Content for Procurement Helps Compare Specs, Risks, and SuppliersTechnical explainer content for procurement helps teams compare specs, uncover supplier risks, and choose solutions that improve compliance, lifecycle value, and long-term performance.
 Jun 29, 2026System Interoperability Testing Vendors: Key Criteria for Compliance and PerformanceSystem interoperability testing vendors compared: discover how to assess compliance, performance, independence, and real-world reliability before costly integration failures happen.
 Jun 28, 2026Product Benchmarking Explained: How to Compare Performance, Cost, and QualityProduct benchmarking explained: learn how to compare performance, cost, and quality with a practical framework that reduces risk, improves supplier selection, and supports smarter long-term decisions.
 Jun 27, 2026How to Build a Product Benchmarking Comparison Matrix for Hospitality Equipment SelectionProduct benchmarking comparison matrix guide for hospitality equipment selection. Learn to compare cost, compliance, durability, and lifecycle value with confidence.
 Jun 25, 2026What Drives System Interoperability Testing Implementation Cost in Multi-Vendor Projects?System interoperability testing implementation cost rises in multi-vendor projects due to scope gaps, retesting, compliance, and downtime risk. Learn how to control costs early.
Quarterly Executive Summaries Delivered Directly.
Join 50,000+ industry leaders who receive our proprietary market analysis and policy outlooks before they hit the public library.