Search News
TerraVista Metrics (TVM)Industry Portal
TerraVista Metrics (TVM)Hot Articles
TerraVista Metrics (TVM)- Industry Reports Library: How to Find Reliable Data for Market ResearchExplore an industry reports library to find reliable market data, verify sources, and compare findings. Learn practical steps to turn research into confident business decisions.
- Do Cracks Around Cabin Joints Require an Engineering Inspection?Do cracks around cabin joints need an engineering inspection? Discover key warning signs, when monitoring is appropriate, and how to choose the right next step before repairs.
- How Do You Verify a Prefab Cabin's Wind-Load Rating?How do I verify a prefab cabin's wind-load rating? Discover the engineering reports, site checks, and anchorage details you need to assess supplier claims and buy with confidence.
Popular Tags
TerraVista Metrics (TVM)Industry NewsSigns a Benchmarking System Is Too Rigid for Daily Use
auth.Time
Oct 15, 2026Click Count
When a benchmarking system becomes too rigid, daily decisions slow down and valuable benchmarking data loses practical impact. For procurement teams, researchers, and business evaluators in tourism infrastructure, effective benchmarking software and benchmarking tools should support fast benchmarking analysis, clear benchmarking comparison, and a flexible benchmarking process. This article explores the warning signs, common operational bottlenecks, and why adaptable benchmarking solutions and benchmarking best practices matter for producing a useful benchmarking report.
Why rigid benchmarking systems fail in real procurement environments
In tourism and hospitality infrastructure, benchmarking is rarely a one-time exercise. Procurement teams compare prefab lodging units, smart hotel systems, energy modules, hardware assemblies, and connected devices across multiple suppliers over 2–8 week evaluation cycles. A rigid benchmarking system usually looks organized on paper, yet it often breaks down when project conditions shift, specifications evolve, or stakeholders ask for a different benchmarking comparison at short notice.
The first problem is lag. If users need repeated admin approval to add metrics, adjust weightings, or create a new benchmarking report, the system becomes an obstacle instead of a decision tool. In real sourcing work, site operators may need thermal performance data one day, IoT network throughput the next, and material fatigue indicators after a supplier revision. A fixed template cannot support that pace.
The second problem is shallow relevance. A rigid benchmarking process often assumes that all projects share identical priorities. That is not how tourism infrastructure works. A remote glamping project may prioritize insulation range, transport dimensions, and maintenance intervals, while an urban hospitality retrofit may focus on system interoperability, power stability, and installation disruption measured over 3–5 working days.
For information researchers and business evaluators, this rigidity creates another risk: benchmarking data may remain technically correct but commercially unusable. If the benchmark cannot reflect carbon compliance, durability verification, lifecycle maintenance, and deployment constraints together, the result does not support a defensible purchase decision. TerraVista Metrics addresses this by treating benchmarking as a practical engineering filter, not a static scorecard.
Common symptoms seen by procurement and evaluation teams
- Benchmarking software requires manual restructuring whenever a new supplier spec sheet arrives, adding 1–3 days to routine comparison work.
- Users can compare only headline numbers, but not context such as test conditions, load range, operating temperature band, or maintenance cycle.
- The benchmarking report cannot separate mandatory thresholds from negotiable preferences, which weakens supplier selection discipline.
- Distributors and agents cannot reuse the same framework across small-batch, mid-volume, and project-based opportunities.
Once these symptoms appear, daily use declines. Teams either bypass the system with spreadsheets or use the benchmarking tool only at final approval stage. That defeats the purpose of continuous benchmarking analysis, especially where engineering and procurement decisions must stay aligned from shortlisting through final negotiation.
What warning signs show a benchmarking process is too rigid?
A useful way to test system flexibility is to ask how fast the framework adapts to a realistic project change. Can your team add 3 new comparison fields within the same day? Can it separate lab data from supplier-declared values? Can it produce different views for technical reviewers, commercial buyers, and channel partners? If the answer is no, the benchmarking system is already too rigid for daily use.
In tourism infrastructure procurement, warning signs appear early. A benchmarking tool may force all products into a single scoring model even when categories are fundamentally different. For example, benchmarking prefab cabins, access control systems, and ride-adjacent hardware under the same logic can distort value. Some products require structural and thermal metrics, while others require latency, throughput, compatibility, and uptime thresholds.
Another warning sign is poor traceability. If users cannot see where a number came from, under what conditions it was tested, and whether it reflects a standard method or supplier claim, the benchmarking comparison loses credibility. Procurement officers need decision evidence that survives internal review, distributor handoff, and cross-border sourcing discussions over 2–4 rounds of negotiation.
TVM’s approach is built around raw engineering metrics and structured interpretation. This matters because a flexible benchmarking process does not mean a loose process. It means the ability to add, remove, prioritize, and validate metrics according to project risk without losing methodological discipline.
A practical benchmark flexibility checklist
The table below helps procurement teams identify whether their current benchmarking software supports daily decision-making or simply stores comparison data. These checkpoints are especially relevant when evaluating tourism hardware with mixed technical, operational, and compliance requirements.
If your current workflow matches the left column more than twice, the issue is not just software usability. It signals a structural weakness in the benchmarking process itself. That weakness tends to increase delays, create inconsistent supplier evaluations, and reduce confidence in the final benchmarking report.
Three questions procurement leaders should ask
- Can the system support 3 categories of metrics at once: technical performance, compliance evidence, and commercial delivery constraints?
- Can we update benchmark logic within 24–48 hours when a supplier changes a component, material, or control system?
- Can our distributor or regional procurement partner understand the comparison without needing the original analyst present?
If not, the benchmarking tool may still generate reports, but it is unlikely to support repeated, daily, multi-party decision cycles.
How rigidity creates operational bottlenecks across tourism infrastructure projects
Benchmarking rigidity rarely stays in the analytics layer. It spreads into procurement timing, supplier communication, technical clarification, and even contract risk. In tourism infrastructure, where projects may combine accommodation modules, smart guest systems, utilities, and recreational hardware, one slow benchmarking step can delay several dependent approvals.
Consider a sourcing team comparing prefabricated guest units from several manufacturers. If the benchmarking comparison cannot separate wall insulation values, corrosion resistance conditions, transport dimensions, and assembly time, the team may shortlist a visually attractive option that later fails logistical or climate requirements. A rigid system often hides such mismatches because it favors a simplified total score over usable engineering detail.
The same issue appears in smart hospitality systems. A hotel operator may need benchmarking analysis for gateway stability, device concurrency, data throughput, and interoperability with existing building systems. If the benchmarking process uses fixed fields built for simpler hardware categories, the report will not capture integration risk. What looks comparable at the dashboard level may be incompatible during deployment.
For dealers, distributors, and agents, operational bottlenecks also affect resale confidence. They need a benchmarking report that can translate technical details into market-ready decision points. If the system cannot produce regionalized or scenario-based comparison outputs within 5–7 business days, channel partners lose momentum and may default to easier but less qualified product options.
Where delays typically appear
- At the data intake stage, when supplier files arrive in different formats and the system cannot normalize them without manual re-entry.
- During technical review, when analysts need to add project-specific criteria such as climatic operating range, vibration tolerance, or maintenance intervals.
- At commercial evaluation, when landed cost, lead time, warranty scope, and spare-parts planning are tracked outside the benchmark.
- Before approval, when leadership needs a concise comparison summary but the system can export only raw detail or a generic total score.
TVM reduces these bottlenecks by framing benchmarking as a modular evidence workflow. Instead of forcing every project into one rigid matrix, the method supports selective depth. Teams can benchmark 4–6 core indicators at early screening, then expand to 10–15 metrics during final evaluation if a shortlisted supplier requires closer scrutiny.
What flexible benchmarking tools should include for daily use
A flexible benchmarking system should not mean endless customization. It should mean controlled adaptability. Daily users need benchmarking tools that preserve comparability while allowing project-specific edits. In practice, that means a stable method for core indicators plus adjustable fields for category risk, deployment conditions, and commercial constraints.
For tourism procurement, good benchmarking software should support at least 4 working layers: baseline product data, test-condition notes, project-specific thresholds, and report-level recommendations. This structure helps teams compare like-for-like data without ignoring the realities of site climate, guest usage intensity, or integration dependencies. It also helps business evaluators explain why two similar products may score differently under different deployment models.
Flexible tools also need version control. Supplier revisions are common during 2–6 week procurement windows, especially when engineering teams request alternate materials or component substitutions. If the benchmark cannot show what changed, when it changed, and whether the revision affects the previous comparison, the team risks approving outdated assumptions.
This is where TVM’s data-driven whitepaper logic becomes valuable. By turning supplier capability into standardized engineering evidence, TVM helps buyers compare products beyond marketing claims. That gives architects, operators, and procurement directors a cleaner basis for benchmark adjustments without losing consistency.
Core capabilities to look for in a daily-use benchmarking solution
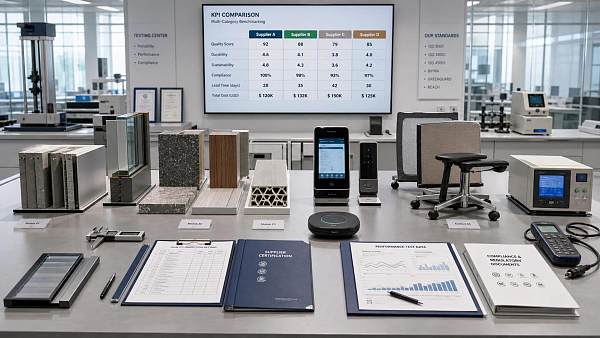
The following comparison table summarizes what decision-makers should prioritize when selecting benchmarking tools for regular procurement, supplier qualification, and channel support. It covers selection, comparison, and service process considerations that frequently shape B2B purchasing outcomes.
When these capabilities are present, benchmarking becomes a working system rather than a reporting archive. The result is not only better benchmarking analysis but also better speed, clearer supplier communication, and stronger commercial defensibility.
A simple 4-step implementation model
- Define 5–8 non-negotiable benchmark criteria tied to project risk, such as durability, energy behavior, integration fit, delivery window, and maintenance burden.
- Add 3–6 adjustable criteria for regional climate, operator preference, guest experience requirements, or distributor support needs.
- Separate data sources into tested values, supplier-declared values, and estimated commercial values to avoid comparison distortion.
- Review the benchmark every 2–4 weeks during active procurement so the framework stays relevant instead of becoming a fixed document.
This model is especially useful when buyers need benchmarking best practices that support both shortlisting and negotiation, not just final-stage documentation.
How to choose the right benchmarking approach for procurement, distribution, and business evaluation
The right benchmarking approach depends on your role in the buying chain. Information researchers need a framework that reveals signal from supplier noise. Procurement managers need a benchmark that converts technical detail into sourcing action. Business evaluators need evidence strong enough for risk review. Distributors and agents need a comparison format that can be reused across prospects without losing precision.
That means selection should begin with workflow needs, not software features alone. If your team handles multiple product families, your benchmarking process should support category-specific modules. If your organization reviews projects across several regions, the system should capture local compliance expectations, climate conditions, and deployment constraints without requiring a full rebuild each time.
For the tourism sector, procurement teams often need to evaluate products across 3 linked dimensions: engineering reliability, operational suitability, and commercial feasibility. Rigid systems usually perform reasonably in only one dimension. Stronger systems connect the three. That connection is what makes a benchmarking report useful for internal approval, external partner communication, and supplier negotiation.
TVM is well positioned here because its role is independent and metric-led. Instead of repeating supplier marketing language, TVM translates technical properties into decision-ready benchmarking outputs. This is particularly valuable when sourcing from manufacturing ecosystems that offer broad capability but inconsistent presentation quality. Standardized whitepapers reduce ambiguity and speed comparison across vendors.
Procurement guidance: what to verify before adopting a system
- Confirm whether the system can benchmark both physical infrastructure and digital hospitality systems without forcing them into the same scoring logic.
- Check whether typical service nodes are clear, such as intake, metric mapping, comparison review, and final reporting within a realistic 7–15 day cycle.
- Ask how the benchmark handles unavailable data, partial test records, or supplier substitutions so that risk is visible rather than hidden.
- Review whether outputs support RFQ preparation, distributor enablement, and management approval, not just analyst reference.
FAQ: practical questions teams often ask
How do we know if benchmarking software is too rigid for our team?
If your team needs parallel spreadsheets, repeated manual adjustments, or separate reports for every stakeholder, rigidity is already affecting daily use. Another sign is when simple changes, such as adding 2–3 new metrics or changing weightings, take longer than one working day. Effective benchmarking tools should support controlled edits without breaking comparison logic.
Which projects benefit most from a flexible benchmarking process?
Projects with mixed technical requirements benefit the most. Examples include prefab tourism accommodation, integrated hotel IoT systems, attraction hardware, and infrastructure packages that combine structural, electrical, and digital elements. In these settings, benchmarking comparison must account for multiple operating conditions, delivery constraints, and maintenance realities.
What should a useful benchmarking report include?
A practical benchmarking report should include at least 4 components: metric definitions, source traceability, comparison conclusions, and procurement implications. It should also separate mandatory thresholds from preferred features. If the report only shows scores without context, it may be neat visually but weak as a decision document.
How often should benchmark criteria be reviewed?
During active sourcing, many teams benefit from reviewing criteria every 2–4 weeks or whenever a supplier revision changes a critical component, material, or integration method. For ongoing category management, a quarterly review is often enough to keep benchmarking best practices aligned with market changes and project feedback.
Why work with TVM for flexible benchmarking and decision-ready reports
When procurement teams source tourism infrastructure, the biggest challenge is rarely access to products. It is access to reliable comparison logic. TerraVista Metrics helps solve that problem by converting supplier capability into raw engineering metrics, structured benchmarking analysis, and practical benchmarking reports that support daily commercial use. This matters when teams need more than a product brochure and less than a full custom consulting engagement every time.
TVM’s value is especially strong for buyers evaluating Chinese manufacturing options across hospitality and tourism applications. The platform works as a structural filter, helping architects, operators, procurement directors, and channel partners see how thermal efficiency, system data performance, material fatigue behavior, and integration readiness compare under a standardized framework. That reduces ambiguity at the exact point where budget, risk, and delivery pressure intersect.
If your current benchmarking system feels too rigid, the next step is not necessarily a full replacement. It may begin with a better comparison architecture, clearer metric hierarchy, or an independent whitepaper that validates what really matters for your project. In many cases, a stronger benchmarking process can reduce rework, improve supplier discussions, and shorten the path from longlist to approved shortlist.
Contact TVM if you need support with parameter confirmation, product selection, supplier benchmarking comparison, delivery-cycle planning, compliance-oriented documentation, sample evaluation logic, or quotation-stage technical clarification. For teams handling complex procurement in 7–15 day windows, or multi-round evaluation over 2–6 weeks, a flexible benchmarking solution can turn scattered data into a faster and more defensible decision.
Recommended News
 Sep 27, 2026How to Design Scalable System Integration Testing for Multi-Vendor DeploymentsScalable system integration testing for multi-vendor deployments: build resilient, secure, and growth-ready operations with proven interface, resilience, and acceptance strategies.
 Sep 24, 2026Hotel Tourism Benchmarking: Which KPIs Reveal Competitive Market Position?Tourism benchmarking for hotels reveals the KPIs that define competitive position, from RevPAR index and demand quality to profit, guest experience, and asset resilience.
 Sep 20, 2026Supply Chain Analysis: How to Identify Cost, Risk, and Lead-Time BottlenecksSupply chain analysis helps tourism project leaders uncover cost, risk, and lead-time bottlenecks—protecting opening dates, budgets, and guest-ready operations.
 Sep 19, 2026How to Choose Industry Benchmarking Tools That Deliver Actionable Performance InsightsIndustry benchmarking tools: learn how to validate data, compare lifecycle costs, assess compliance, and turn performance evidence into smarter decisions.
 Sep 14, 2026Engineering Performance Testing Trends Reshaping Product Validation WorkflowsEngineering performance testing trend analysis reveals how assembly validation, realistic environmental loads, and digital resilience improve product reliability and reduce field failures.
 Sep 12, 2026Cloud Integration Interoperability Testing: Methods, Metrics, and Release GatesSystem interoperability testing cloud integration: explore practical methods, key metrics, and evidence-based release gates for secure, reliable connected operations.
 Sep 05, 2026What Engineering Performance Testing Should Cover During a Specification ReviewEngineering performance testing for specification review: learn how to verify structural strength, durability, safety, sustainability, and system reliability before costly project decisions.
 Aug 11, 2026How to Evaluate Materials Performance Analysis Services in Europe for Compliance-Critical ProjectsMaterials performance analysis Europe: learn how to compare accredited labs, verify compliance readiness, and choose a provider whose data, methods, and reports stand up to real project scrutiny.
 Jul 27, 2026Product Application Analysis for Procurement: How to Compare Fit, Risk, and ROIProduct application analysis for procurement helps buyers compare fit, compliance risk, lifecycle cost, and ROI with confidence. Learn a practical framework to avoid costly sourcing mistakes.
 Jul 22, 2026How to Evaluate Weather Resistance in Materials Performance Analysis?Materials performance analysis weather resistance explained: learn how to assess UV, moisture, temperature, and corrosion risks to choose durable materials with confidence.
 Jul 15, 2026Cloud Storage for Business: How to Compare Security, Access Speed, and Backup CostsCloud storage for business: compare security, access speed, and backup costs with a practical framework to reduce risk, control spend, and choose the right provider with confidence.
 Jul 14, 2026What Are Standardized Performance Benchmarks Ratings Used For in Vendor Evaluation?Standardized performance benchmarks rating explains how buyers compare vendors with verified data on compliance, durability, and lifecycle value for smarter procurement decisions.
 Jul 13, 2026Product Benchmarking Rating Explained: How to Compare Scores Across SuppliersProduct benchmarking rating explained: learn how to compare supplier scores with confidence, verify methodology, spot hidden risks, and make smarter procurement decisions.
 Jul 13, 2026How to Choose a Product Benchmarking Data Provider for Reliable Market ComparisonsProduct benchmarking data provider selection starts with methodology, transparency, and sector fit. Learn how to compare providers for reliable market insights and smarter procurement decisions.
 Jul 10, 2026Technical Integration Resilience Explained: How to Reduce Downtime Across Connected SystemsTechnical integration resilience explained: learn how to reduce downtime, prevent cascading failures, and improve uptime across connected systems with practical planning insights.
 Jul 08, 2026How to Use Product Benchmarking KPIs to Compare Competing SolutionsProduct benchmarking KPIs help you compare competing solutions with real evidence. Learn how to measure performance, lifecycle cost, compliance, and risk for smarter buying decisions.
 Jul 05, 2026How to Run an Environmental Sustainability Assessment: Metrics, Boundaries, and Trend AnalysisEnvironmental sustainability assessment trend analysis made practical: learn how to set metrics and boundaries, compare lifecycle impacts, and turn sustainability data into smarter decisions.
 Jul 04, 2026Hospitality Design Benchmarks Metrics Explained: Which KPIs Matter for Guestroom Upgrades?Hospitality design benchmarks metrics explained: discover the KPIs that matter most for guestroom upgrades, from lifecycle cost and durability to energy use, maintenance, and guest satisfaction.
 Jul 02, 2026How to Compare Product Category Pricing Models for Better Margin PlanningProduct category pricing model comparison made practical: learn how to evaluate total cost, hidden risks, and lifecycle value to improve margin planning and make smarter sourcing decisions.
 Jun 30, 2026How Technical Explainer Content for Procurement Helps Compare Specs, Risks, and SuppliersTechnical explainer content for procurement helps teams compare specs, uncover supplier risks, and choose solutions that improve compliance, lifecycle value, and long-term performance.
 Jun 29, 2026System Interoperability Testing Vendors: Key Criteria for Compliance and PerformanceSystem interoperability testing vendors compared: discover how to assess compliance, performance, independence, and real-world reliability before costly integration failures happen.
 Jun 28, 2026Product Benchmarking Explained: How to Compare Performance, Cost, and QualityProduct benchmarking explained: learn how to compare performance, cost, and quality with a practical framework that reduces risk, improves supplier selection, and supports smarter long-term decisions.
 Jun 27, 2026How to Build a Product Benchmarking Comparison Matrix for Hospitality Equipment SelectionProduct benchmarking comparison matrix guide for hospitality equipment selection. Learn to compare cost, compliance, durability, and lifecycle value with confidence.
 Jun 25, 2026What Drives System Interoperability Testing Implementation Cost in Multi-Vendor Projects?System interoperability testing implementation cost rises in multi-vendor projects due to scope gaps, retesting, compliance, and downtime risk. Learn how to control costs early.
Quarterly Executive Summaries Delivered Directly.
Join 50,000+ industry leaders who receive our proprietary market analysis and policy outlooks before they hit the public library.