Search News
TerraVista Metrics (TVM)Industry Portal
TerraVista Metrics (TVM)Hot Articles
TerraVista Metrics (TVM)- How to Evaluate Spark Plug Suppliers for Consistent Quality and Lead TimesSpark plugs supplier evaluation guide: compare quality control, traceability, fitment, total cost, and reliable lead times to secure dependable engine maintenance supply.
- What Drives System Interoperability Testing Service Costs in Complex Projects?System interoperability testing service cost depends on integration scope, workflows, environments, and assurance needs. Learn how to budget smarter and reduce project risk.
- Project Planning Sourcing Guides: How to Qualify Suppliers Before Work StartsSourcing guides project planning helps teams qualify suppliers before work begins—verify compliance, delivery capacity, financial strength, and sustainability to reduce risk and protect project outcomes.
Popular Tags
TerraVista Metrics (TVM)Industry NewsSystem Integration Testing for Device Integration: Key Interfaces and Failure Risks
auth.Time
Oct 07, 2026Click Count
What System Integration Testing Must Prove Before Devices Go Live
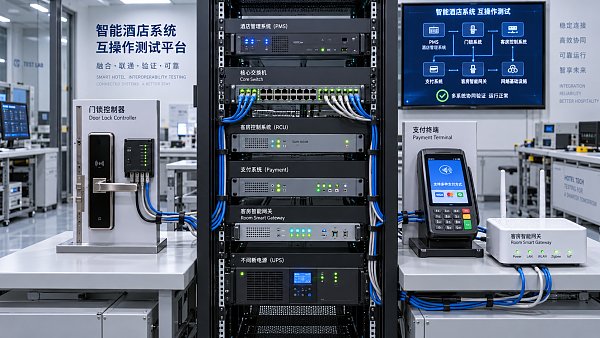
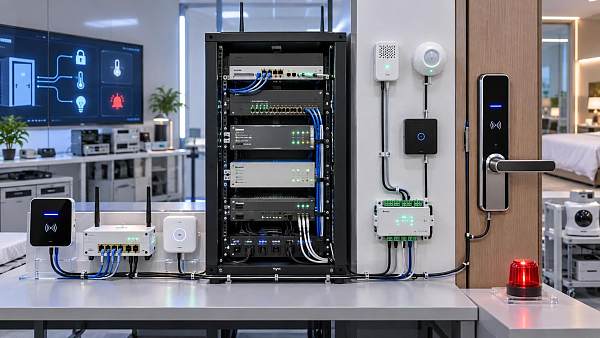
System integration testing for device integration should answer a practical question: will independently supplied devices continue to operate correctly when they exchange data, commands, identities, and alarms inside the live operating environment?
That question is more demanding than confirming that each device powers on, connects to a network, or passes its own factory acceptance test. A smart lock can function correctly on a bench yet fail to update access rights after a property-management-system change. An occupancy sensor can report data reliably until a gateway restarts. An attraction controller can accept a command from its local panel while rejecting the same command through the supervisory platform. These are integration failures, and they tend to emerge at the boundaries between systems rather than inside a single product.
For technical evaluators, the priority is to validate the interfaces that carry operational consequence. In tourism, hospitality, leisure, and distributed-site environments, those consequences may include denied guest access, unavailable rooms, interrupted safety functions, inaccurate energy controls, maintenance blind spots, or loss of audit evidence. A credible integration test therefore examines behavior across the entire transaction path, including abnormal conditions, recovery, and change management.
Start With the Operational Transaction, Not the Device List
Device inventories are useful for procurement, but they are a weak starting point for system integration testing. A list may show locks, thermostats, gateways, kiosks, sensors, controllers, payment terminals, and management software. It does not show what must happen across those components when a guest checks in, when a room is taken out of service, when a safety alarm occurs, or when an asset loses connectivity.
The more useful unit of testing is the operational transaction. Each transaction should define a trigger, the participating systems, the data exchanged, the expected result, the maximum acceptable delay, the audit record, and the fallback behavior.
- A guest is assigned a room, and the access-control platform must receive an authorized credential within the agreed workflow.
- A room changes from vacant to occupied, and environmental controls may adjust without overriding manual guest settings or breaching energy-management rules.
- A connected asset reports a fault, and the maintenance platform must create or route an actionable event with a device identity, location, severity, and timestamp.
- A booking is cancelled or a guest is checked out early, and access rights, service requests, and associated device states must be removed or updated in the correct order.
- A network segment fails, and local devices must move to an approved degraded mode without creating unsafe or misleading states.
This approach exposes a common weakness in device integration programs: interface testing often stops after a successful “happy path” demonstration. The device receives a command, the screen changes, and the demonstration is treated as evidence of readiness. Yet the operating environment is defined by exceptions. Duplicate messages, incomplete payloads, delayed synchronization, expired credentials, backend restarts, daylight-saving changes, and simultaneous commands are all more revealing than a clean first-time connection.
The Interfaces That Carry the Highest Risk
Not every interface deserves the same depth of scrutiny. Test effort should follow operational impact and the degree of coupling between systems. Four interface categories usually require early attention.
Identity and authorization interfaces
Identity is frequently distributed across several platforms: a booking or property-management system, an identity provider, a mobile application, an access-control platform, staff administration tools, and sometimes third-party service applications. The central question is not simply whether a user can authenticate. It is whether permissions are accurate, timely, limited to the correct scope, and withdrawn when the underlying status changes.
Test cases should include new creation, modification, revocation, temporary access, duplicate identities, offline use, and delayed synchronization. Evaluators should also determine the authoritative source of each identity attribute. If both the hotel platform and the lock-management system can alter access validity, conflicting updates may leave a credential active longer than intended or revoke a legitimate credential unexpectedly.
Authorization failures can also arise from weak time handling. Devices, gateways, and cloud services may use different time sources or time zones. A credential or maintenance window that appears valid in one system can be rejected by another when clocks drift or local time changes. Time synchronization, timestamp formats, and expiry rules should be treated as integration requirements rather than background infrastructure details.
Command and control interfaces
Devices that receive commands introduce a different class of risk. A command is not complete merely because it has been transmitted. The receiving device must interpret it correctly, apply it safely, report its actual resulting state, and avoid executing it twice when messages are retried.
This distinction matters for room controls, gates, lifts, lighting systems, irrigation, attraction equipment, and other physical assets. A management platform may display “command accepted” even when the field device has not moved to the intended state. Testing should differentiate acknowledgement of receipt, acknowledgement of processing, and confirmation of physical outcome.
Technical evaluators should request clarity on command ownership. When a local controller, a central management platform, an operator interface, and an automated rule can all issue instructions, the system needs a defined precedence model. Without one, devices may oscillate between states, override local safety logic, or generate a continuous sequence of alarms and corrective commands.
Telemetry, alarms, and event interfaces
Connected devices produce more than measurements. They also produce quality indicators, fault conditions, communication status, configuration changes, and maintenance signals. These events are often transformed before they reach the platform used by operators. A gateway may aggregate them, middleware may map them to another schema, and dashboards may apply their own severity categories.
That chain creates room for silent loss of meaning. A fault code can arrive as a generic “offline” event. A temperature reading can be displayed without units or calibration context. A recurring alert can be deduplicated so aggressively that the operator sees no indication of a persistent condition. Integration testing should trace representative events from source to final workflow and verify that the event remains identifiable, time-ordered, interpretable, and actionable.
Alarm flooding deserves specific tests. Under fault conditions, large numbers of sensors or controllers can report simultaneously. The relevant question is whether message queues, gateways, and receiving applications preserve priority events when traffic rises. A platform that looks responsive under normal load may be unable to surface the first safety-relevant signal during a widespread communications or power incident.
Data-model and lifecycle interfaces
Many integration defects are data-model defects. Systems may use different names and identifiers for the same room, cabin, asset, guest, zone, or maintenance item. One application may classify a unit by marketing name, another by building-floor-room hierarchy, and a third by a device serial number. Manual mapping can make the system appear functional during commissioning while leaving it fragile after refurbishment, expansion, or asset replacement.
A sound test program confirms how objects are created, matched, changed, retired, and retained. It should answer questions such as: What happens when a cabin is renumbered? Can a failed controller be replaced without losing its service history? Does a room split into two operational zones create duplicate records? Are deleted records actually removed from downstream systems, or simply hidden in the source platform?
The need for lifecycle testing is especially strong in modular accommodation, temporary installations, and multi-site operations. Physical assets can be moved, recommissioned, or replaced more often than enterprise software teams expect. Integration design must accommodate those changes without relying on undocumented manual corrections.
Failure Modes Often Missed During Acceptance Testing
The most expensive integration failures are rarely caused by a complete outage alone. Partial failure is harder to detect and more likely to create incorrect decisions. A device may remain reachable while reporting stale data. A gateway may queue commands but never deliver them after reconnecting. A cloud service may accept updates while a local controller continues to use an older configuration.
- Duplicate delivery: Retries after a timeout can produce repeated check-in events, duplicate work orders, or multiple actuation requests. Interfaces need idempotency rules or transaction identifiers.
- Out-of-order messages: A later status update may reach the platform before an earlier command. Systems must avoid treating an older message as the latest state.
- Schema drift: A supplier update can add, remove, rename, or reinterpret fields. Interfaces may remain technically available while downstream logic fails or discards important information.
- Offline and recovery behavior: Devices may continue operating locally, fail closed, fail open, or use cached permissions. Each behavior has operational and safety implications that require explicit approval.
- Configuration mismatch: Network addresses, certificates, firmware versions, device profiles, and location mappings can differ between test and production environments.
- Capacity degradation: An interface may perform acceptably with a small pilot but slow down when devices reconnect together after a service interruption.
- Observability gaps: Logs may show that a message left one platform but provide no evidence that the receiving system processed it successfully.
Security testing also belongs inside the integration scope when devices exchange operational data or accept remote commands. A secure individual device does not guarantee a secure integrated system. Credentials may be exposed in middleware configuration, certificates may not rotate correctly, service accounts may have excessive privilege, or an API may allow one property or site to query another. Evaluators should test authorization at the interface level, including invalid tokens, expired credentials, malformed requests, and attempts to invoke commands outside the approved role.
How to Make the Test Evidence Useful for a Procurement Decision
A procurement team needs more than a supplier statement that an API is available or that a protocol is supported. Protocol compatibility is only the entry condition. Two systems can both support the same protocol while differing in message profiles, data semantics, optional features, error handling, rate limits, version support, and security configuration.
Before approval, technical evaluators should seek evidence that maps directly to the intended deployment. The evidence package should include interface specifications, supported versions, field definitions, ownership rules, dependency diagrams, expected failure behavior, and a record of the scenarios actually tested. Test results should identify the environment, software and firmware versions, network assumptions, test data, observed outcome, and unresolved limitations.
Acceptance criteria should also distinguish defects from operational constraints. A known delay in non-critical environmental telemetry may be acceptable if it is documented and does not affect control decisions. A delay in revoking access rights or delivering a safety alarm is a different matter. Treating both as generic “integration issues” weakens risk assessment.
There is also value in requiring repeatable tests rather than one-off demonstrations. When an integration depends on configuration files, custom mappings, or vendor-managed middleware, the organization should be able to reproduce the critical tests after upgrades, device replacements, site expansions, and cybersecurity changes. This does not require every test to be fully automated, but the essential workflows should be documented well enough to establish whether a later change has altered system behavior.
Prioritize Recovery and Change, Not Just Initial Connectivity
Initial integration proves that systems can work together under controlled conditions. It says much less about whether they will remain interoperable through ordinary operational change. Device fleets receive firmware updates. Hotel platforms change room status rules. Network certificates expire. A new building wing is added. A supplier changes a cloud endpoint or deprecates an API version. Each change can disrupt an interface that appeared stable during handover.
For this reason, the final test focus should be recovery and change control. Can the system reconcile missed events after connectivity returns? Can an old device and a new firmware version operate together during a phased rollout? Is there a rollback path when an interface update changes message behavior? Can operations staff identify which system owns a fault without relying on several suppliers to interpret fragmented logs?
System integration testing for device integration is most valuable when it turns these questions into verifiable acceptance conditions. The objective is not to prove that every device is sophisticated or that every interface is permanently fault-free. It is to establish which operational outcomes the integrated system can reliably support, how it behaves when dependencies fail, and whether the organization has enough evidence to manage change after commissioning.
Recommended News
 Oct 08, 2026What Drives System Interoperability Testing Service Costs in Complex Projects?System interoperability testing service cost depends on integration scope, workflows, environments, and assurance needs. Learn how to budget smarter and reduce project risk.
 Oct 03, 2026Verified Performance Certification: What It Proves During Product QualificationVerified performance certification helps teams qualify products with confidence. Learn how to assess scope, test conditions, and delivery controls before approval.
 Oct 01, 2026Multiaxial Material Fatigue Analysis for Predicting Service Life Under Variable LoadsMultiaxial material fatigue analysis helps predict service life under variable loads, enabling safer procurement, lower lifecycle risk, and durable tourism infrastructure.
 Sep 28, 2026What Does Tourism Destination Infrastructure Cost? A Budgeting Guide for DevelopersTourism destination infrastructure price guide for developers: budget utilities, systems, installation, lifecycle costs, and contingencies for smarter investments.
 Sep 26, 2026Regulatory Compliance Procurement Support: How to Vet Suppliers Before Contract AwardRegulatory compliance procurement support helps buyers vet suppliers, verify evidence, manage risks, and secure compliant assets before contract award.
 Sep 15, 2026System Integration Testing for Device Integration: Key Interfaces and Failure RisksSystem integration testing device integration: identify critical interfaces, hidden failure risks, recovery gaps, and acceptance evidence before connected devices go live.
 Sep 01, 2026How to Use a Tourism Standards Database to Verify Safety and Compliance RequirementsTourism standards database guide: verify safety, compliance, evidence scope, test conditions, and jurisdiction requirements with confidence.
 Aug 31, 2026Material Performance Validation: Tests and Acceptance Criteria for Critical PartsMaterial performance validation: discover essential tests and acceptance criteria that help critical parts withstand loads, corrosion, fatigue, and real-world service conditions.
 Aug 26, 2026What Is a CMS and How Do You Choose One for a Growing Business Website?CMS explained for growing business websites: learn how to choose a CMS that supports SEO, workflows, integrations, and long-term scalability without costly rebuilds.
 Aug 24, 2026How to Build a Technical Procurement Content Workflow for Faster Vendor EvaluationTechnical procurement content workflow strategies for faster vendor evaluation: standardize intake, compare evidence clearly, surface risks early, and cut costly procurement delays.
 Aug 20, 2026How to Evaluate Sustainable Concrete Alternatives for Low-Carbon Building ProjectsSustainable concrete alternatives: learn how to compare carbon data, structural performance, code compliance, and supply risk to choose low-carbon concrete solutions with confidence.
 Aug 17, 2026What Does Product Category Insights Reveal About Buyer Demand and Market Positioning?Product category insights reveal buyer demand, key product attributes, and market positioning. Learn how to spot reliable signals, compare segments, and make smarter decisions.
 Aug 13, 2026How to Use Industry Benchmarking to Improve Specification Planning DecisionsIndustry benchmarking for specification planning helps technical evaluators make smarter procurement decisions, reduce risk, and improve long-term performance with evidence-based standards.
 Aug 12, 2026Technical Certification Pricing Model: What Drives Cost and How to Compare QuotesTechnical certification pricing model explained: learn what drives cost, spot hidden risks in low quotes, and compare certification proposals with confidence before you approve budget.
 Aug 09, 2026How to Evaluate Tourism Equipment for Eco Resorts Without Compromising Guest ExperienceTourism equipment evaluation for eco resorts made practical: learn how to balance sustainability, durability, and guest comfort to avoid costly mistakes and choose smarter.
 Aug 07, 2026How to Evaluate LEED Standards for Environmental Sustainability in Building ProjectsEnvironmental sustainability assessment LEED standards explained: learn how to evaluate prerequisites, credits, costs, and project risks to achieve smarter, more reliable green building outcomes.
 Aug 05, 2026Why Eco Structures in the Middle East Are Shifting Toward Modular, Off-Grid DesignsEco structures in Middle East markets are moving to modular, off-grid designs for faster delivery, lower operating risk, and stronger climate resilience. Discover what is driving the shift.
 Jul 30, 2026Industry Insights for Market Expansion: How to Identify High-Potential Regions?Industry insights for market expansion: learn how to identify high-potential regions by assessing demand, infrastructure, compliance, and supply chain readiness for smarter growth.
 Jul 14, 2026How to Apply a Tourism Innovation Validation Framework to Assess New Visitor ProjectsTourism innovation validation framework explained: learn how to assess new visitor projects, reduce delivery risk, verify compliance, and make smarter investment decisions.
 Jul 13, 2026Import Market Research Checklist: How to Assess Demand, Tariffs, and Supplier RiskImport market research made practical: learn how to assess real demand, model tariffs, and reduce supplier risk with a clear checklist for smarter sourcing decisions.
 Jul 11, 2026Fade Resistant Durability: Which Test Methods Matter for Long-Term Outdoor Use?Fade resistant durability starts with the right test data. Discover which methods best predict long-term outdoor performance, color stability, and lower lifecycle risk.
 Jul 09, 2026Electronic Gadgets for Travel and Daily Use: How to Pick Features That MatterElectronic gadgets for travel and daily use should deliver real value. Learn how to compare battery life, portability, durability, and connectivity before you buy.
 Jul 08, 2026Regulatory Compliance Framework Explained: Core Elements, Gaps, and Audit ReadinessRegulatory compliance framework explained for modern organizations: learn core elements, common gaps, and audit readiness strategies to reduce risk, improve control, and strengthen decisions.
![]() Jul 07, 2026Faucets and Mixers Buying Guide: Types, Valve Options, and Finish SelectionFaucets and mixers buying guide covering fixture types, valve options, and finish selection. Compare durability, comfort, maintenance, and performance before you buy.
Quarterly Executive Summaries Delivered Directly.
Join 50,000+ industry leaders who receive our proprietary market analysis and policy outlooks before they hit the public library.